{{ module.title }}
{{ module.desc }}
Hand-coded, point-to-point ETL jobs built one source at a time.
Data engineering teams onboarding new sources continuously.
Generated pipelines, quality checks on every run, and lineage by default.
{{ module.overview }}
Why this module matters
{{ module.problem }}
{{ c }}
{{ module.label }}, end to end
{{ module.howItWorks }}
Hover any stage below to pause and inspect it — the flow keeps moving on its own otherwise.
Key capabilities
{{ cap }}
{{ module.label }} in the platform
A closer look at the screens your team will use day to day.
Pipeline selection — pick portfolios and pipelines, then validate before running
Live execution monitor — step-by-step progress with streaming logs
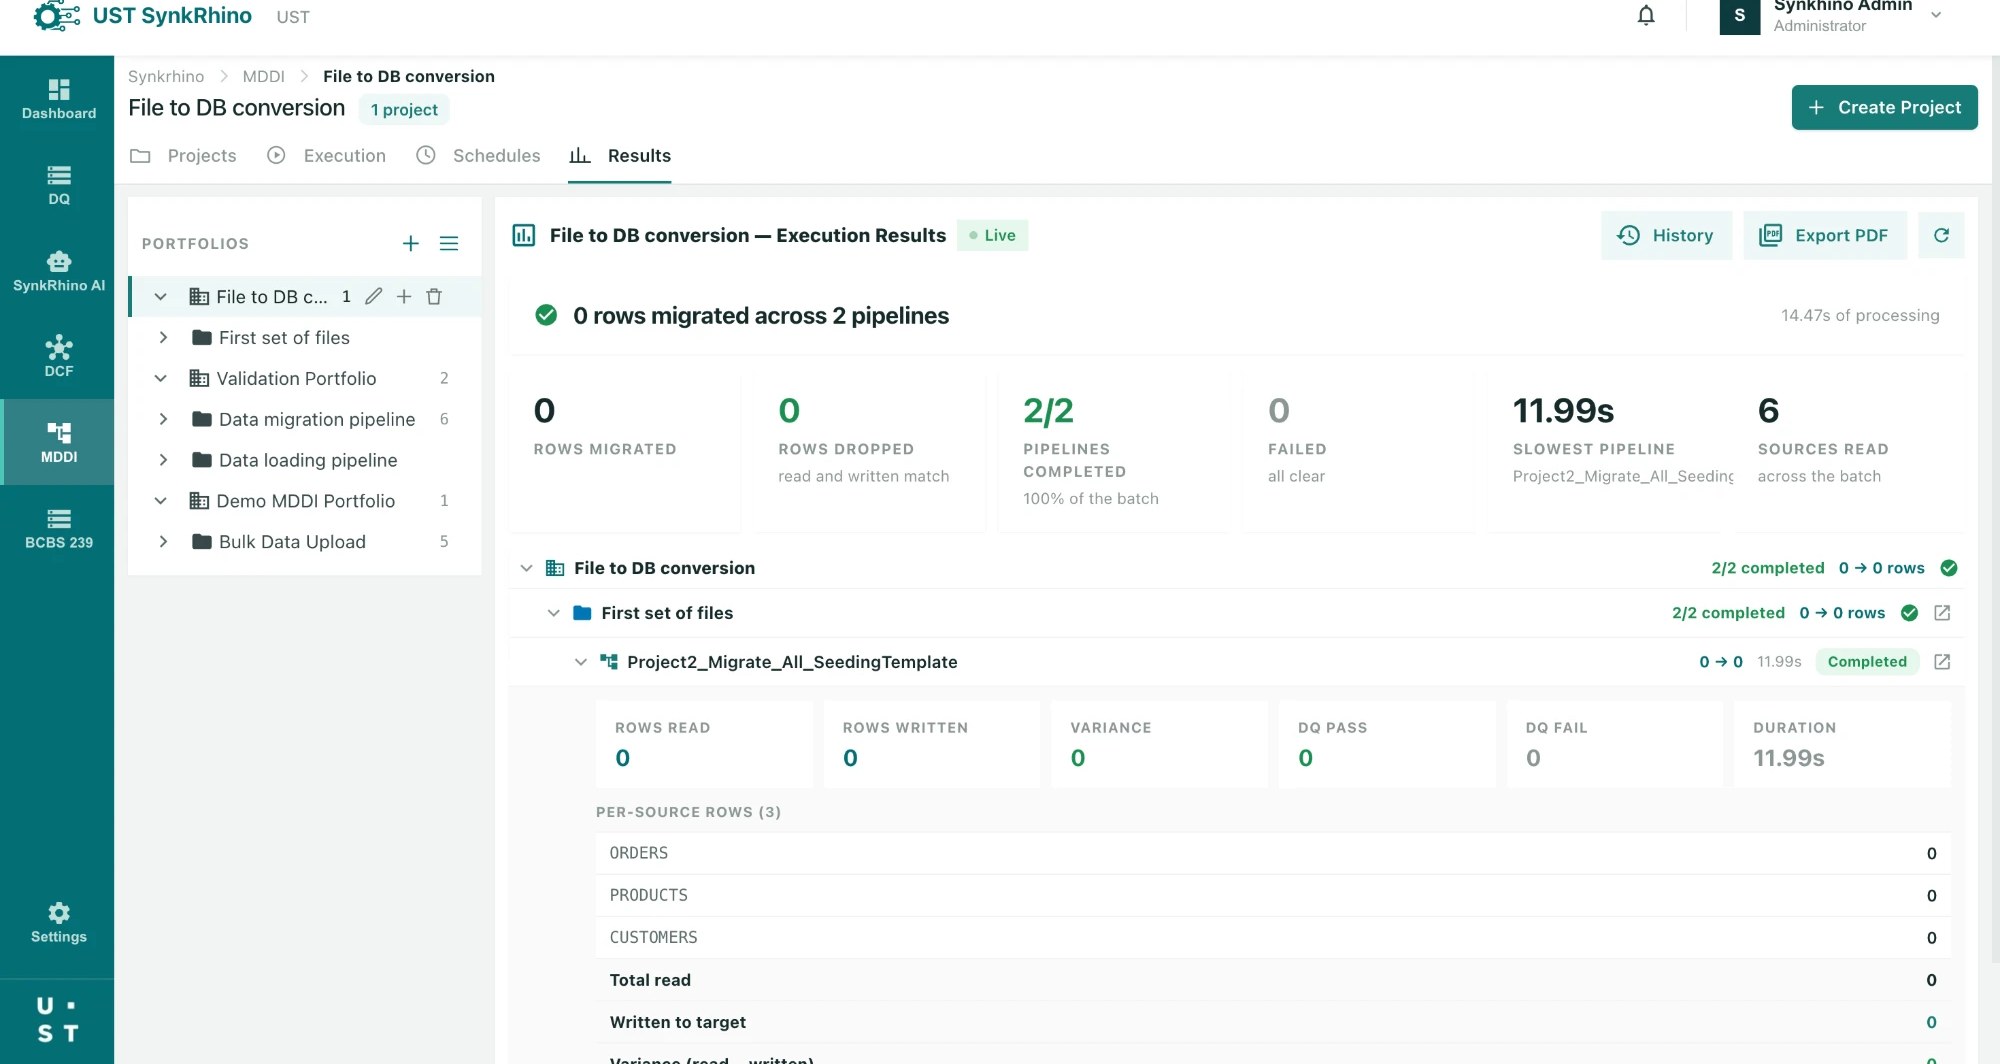
Results dashboard — rows migrated, dropped and per-source breakdown across a batch
Run history — revisit any past batch and reload its results
Scheduling — automate recurring pipeline runs on an hourly, daily or weekly cadence
{{ module.label }} explainer video
A short walkthrough of how {{ module.label }} works, end to end.
{{ module.caseTitle }}
{{ module.caseDesc }}
{{ module.caseOutcome }}
Explore the other modules
Each module stands alone, and they share one metadata layer when you run them together.
See {{ module.label }} in action
Understand how {{ module.label }} can accelerate your data modernization program.